Shorter schedule
For example, an optimization or porting project that typically takes six months can be delivered in about two months, bringing your product to market months earlier.
One-third the time. Higher quality and performance.
Fixstars engineers and our own secure AI agents port AI models and applications to embedded devices and optimize them on the target hardware, delivering high-quality, high-performance software in one-third the usual development time.
Development time
For example, an optimization or porting project that typically takes six months can be delivered in about two months, bringing your product to market months earlier.
No rush fees. You pay the same as you would for a standard-schedule project.
Rigorous testing ensures quality while maximizing hardware performance. A shorter schedule never means cutting corners on quality or performance.
* Schedules and pricing vary by scope. You will get a specific estimate as part of a free assessment.
We optimize software and port it to embedded devices on shorter schedules. End-to-end support: on-device benchmarks, model accuracy validation, and ongoing performance improvements after delivery.
Make your existing system several times faster.
Typical workloads
Port AI models and applications to embedded devices and validate performance on real hardware.
Supported platforms


We support a wide range of other processors, FPGAs, and DSPs beyond the examples above. Contact us to discuss your target platform.
All Fixstars engineers use a dedicated AI agent environment for optimization and porting. Our performance specialists developed it in-house and improve it daily. It goes well beyond what general-purpose AI coding tools can do.
Unlike general-purpose AI coding tools, the environment already carries chip-specific optimization patterns, quantization strategies, and performance-measurement know-how.
Our proprietary knowledge from two decades of optimization projects is built in, and the agents draw on it as they work.
Dedicated optimization and porting specialists improve the environment every day, so our engineers keep getting more productive.
Your project
AI agent environment for optimization & porting
Fixstars Vega: in-house AI platform
Run on our own on-premises hardware
Deliver only approved work
Fixstars engineers own the design, technical decisions, and code reviews, combining AI speed with professional quality.
AI agents write the tests we used to skip for lack of time. Combined with engineer reviews, this reduces rework and defects escaping to the field.
Deliverables include test results, benchmarks, and design documentation, so your team can maintain and extend the software after handoff.
All Fixstars engineers use this workflow. Before development, we agree with you on quality criteria, the test approach, and performance targets.
The AI agents used for development run on infrastructure we operate ourselves. Your specifications, source code, and data are never sent to external AI services.
All AI processing stays on Fixstars' own servers. We run open-weight LLMs on our own hardware.
Nothing you send us reaches an outside service, and nothing is used to train external AI models.
NDAs, handling of confidential information, and ownership of deliverables follow the same framework as our existing contract development work.
We run a GPL contamination checker over the source code we deliver, confirming that no GPL-licensed code has made its way in.
Contact us to discuss access controls, audit support, and other requirements under your security policies.
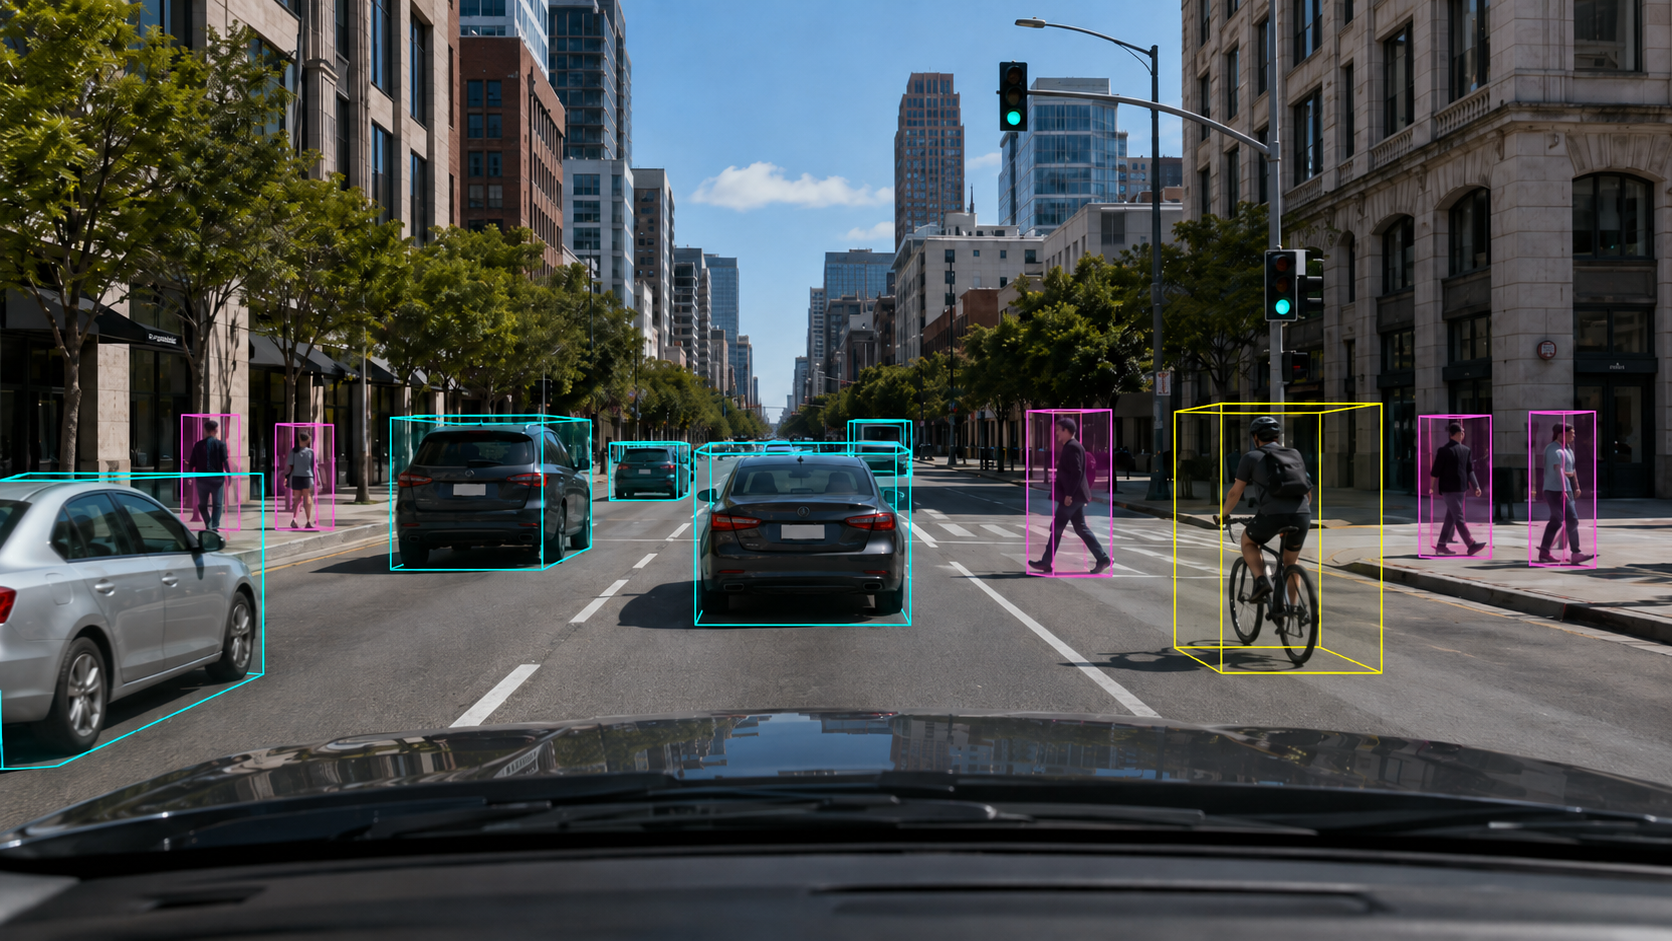
Fixstars engineers and AI agents optimized inference for SparseDrive, an open-source 3D object detection model for autonomous driving. We compared this approach with hand-optimization.
1 person-week
Development effort (manual: ~2 person-months) *1
3.95×
Inference speedup (162.3 → 41 ms/iteration)
Approach: using our in-house AI platform, we deployed the model with TensorRT, applied post-training weight quantization (PTQ) *2, and integrated custom CUDA kernels as TensorRT plugins. The result was a larger speedup than hand-optimization achieved, at a fraction of the engineering effort.
*1 Timeline achieved by a single engineer already experienced with deploying this model. *2 Accuracy: mAP 0.428 → 0.417 due to PTQ; we expect calibration to recover this. Hand-optimization retained 0.428.
It walks through the workloads we targeted, the optimization techniques applied, and the measurement conditions and results, with the numbers. Alongside this case, it also covers accelerating an image segmentation pipeline.
20+ years
In software performance engineering
100+ companies
Supported
99%+
Customer repeat rate
Learn more about what sets Fixstars apart
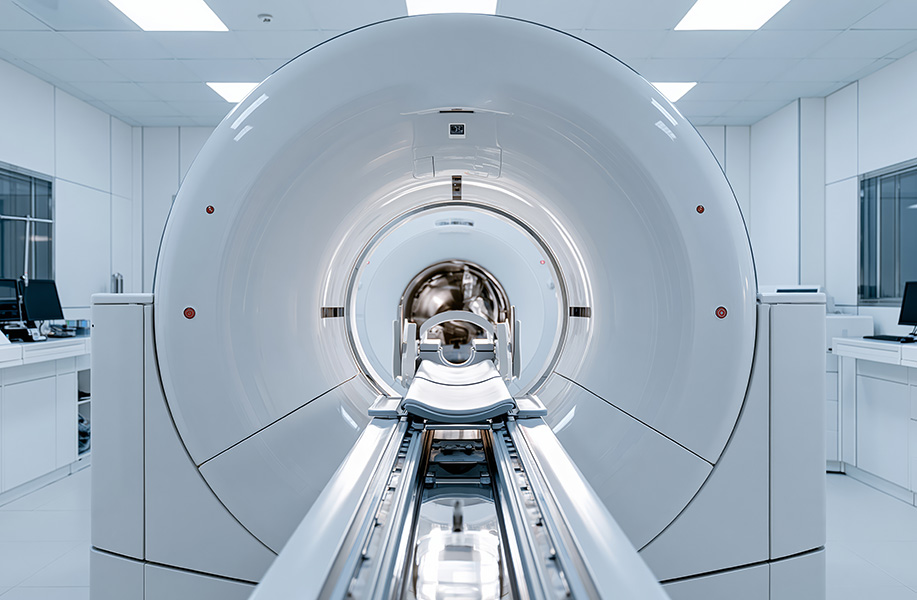
CT image reconstruction runs tens of times faster than with conventional methods, bringing midrange scanners up to the performance of competing high-end systems.
Co-developed GENESIS for R-Car, an AI development toolset that streamlines model compression and optimization for Renesas' automotive SoC.
Fixstars AIBooster was adopted for AFEELA's autonomous-driving AI training environment, improving GPU compute efficiency.
We also have extensive performance-optimization and development experience across industrial equipment, semiconductors, finance, life sciences, and more.
01
We review the workload, its current performance, and the target environment, then estimate what performance is achievable and how much time you can save.
02
We agree with you on the schedule, test approach, performance targets, and cost before development begins.
03
Fixstars engineers and AI agents work together, sharing progress and deliverables weekly.
04
We deliver working software along with test results, benchmarks, and design documentation.
Tell us which workload you want to accelerate or which model or application you need to port to an edge device. In a free assessment, we estimate how much time you would save, what performance is achievable, and what it would cost.
Request a Free AssessmentWhat we need from you